BS-seq数据分析
BS-seq 是检测基因组甲基化的金标准, 用重亚硫酸盐对 DNA 样本进行处理, 甲基化的胞嘧啶(C)位点不会变化,但是没有甲基化的胞嘧啶(C)会被转化成胸腺嘧啶(T)
有多种软件可以对测序数据进行分析
本文介绍bsmap-viewbs-methylkit的流程。
1.1 软件
Section titled “1.1 软件”linux 安装:
bsmap conda install bsmap
samtools conda install samtools=1.15.1
methratio.py 提取 bsmap 结果的 python 脚本,依赖 python2
viewbs conda create -n env4viewbs -c bioconda viewbs
fastp conda install fastp
R 包:
methylkit BiocManager::install('methylKit')
1.2 数据
Section titled “1.2 数据”以 15 天的大豆根、根瘤的甲基化测序数据为例

用 fastp 去除低质量的 reads
ls *gz | cut -d "_" -f 1-3 |sort -u | while read id;donohup fastp -i ${id}_R1.fq.gz -I ${id}_R2.fq.gz -o ${id}_clean_R1.fq.gz -O ${id}_clean_R2.fq.gz -j ${id}.json -h ${id}.html &done
2.1 将测序数据比对到基因组
Section titled “2.1 将测序数据比对到基因组”bsmap -a node_D15_rep1_clean_R1.fq.gz -b node_D15_rep1_clean_R2.fq.gz \-d /path/to/genome.fa \ #参考基因的fasta序列-o node_D15_rep1.bam \ #输出文件-p 20 \ #线程数-v 0.04 \ #错配率-w 1 -r 0 \ #只保留唯一比对的结果2> node_D15_rep1.log \2.2 将结果排序,合并
Section titled “2.2 将结果排序,合并”#排序ls *bam | cut -d '.' -f 1|while read iddonohup samtools sort -@ 8 -o ${id}.sort.bam ${id}.bam &done#合并ls *sort.bam|cut -d '_' -f 1-2|while read id;donohup samtools merge -@ 8 -c ${id}.merge.bam ${id}_rep1.sort.bam ${id}_rep2.sort.bam &done2.3 从 bam 文件中提取每个 C 位点的甲基化信息
Section titled “2.3 从 bam 文件中提取每个 C 位点的甲基化信息”ls *bam|cut -d '.' -f 1|while read id;donohup python methratio.py \-d /path/to/genome.fa \-o ${id}.txt \-u -r -z ${id}.bam &done结果如下:
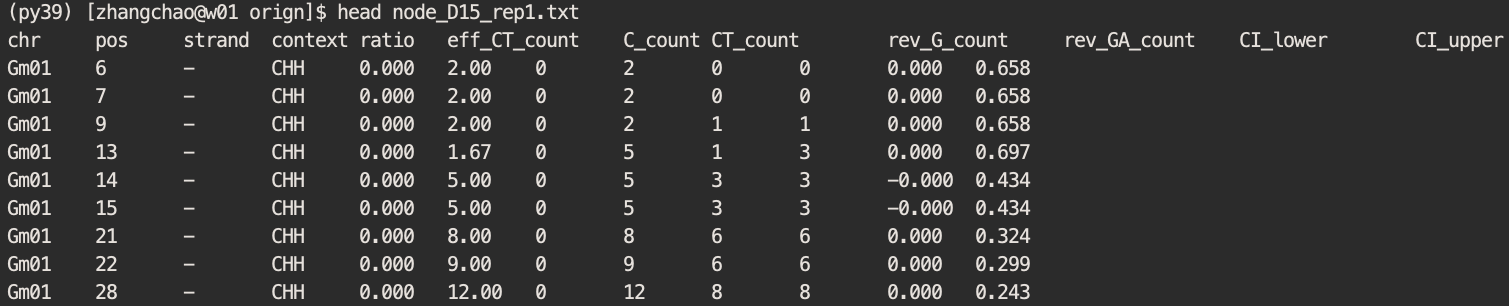
第 7 列是该位点检测为 mC 的 reads,第 8 列是覆盖该位点的所有 reads
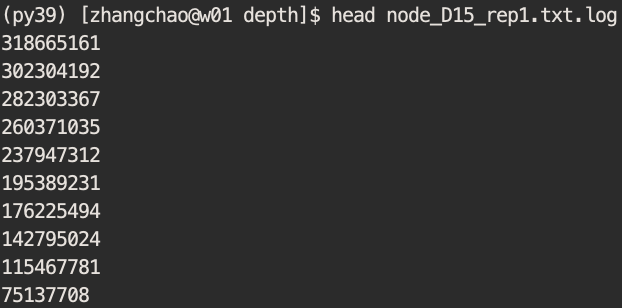
2.4 计算 C 位点覆盖率
Section titled “2.4 计算 C 位点覆盖率”ls *.txt | sort -u | while read id;docat ${id} |sed '1d' |awk -F'\t' '{if($8>=1){print $0}}' | wc -l >>depth/${id}.log;cat ${id} |sed '1d' |awk -F'\t' '{if($8>=2){print $0}}' |wc -l >>depth/${id}.log;cat ${id} |sed '1d' |awk -F'\t' '{if($8>=3){print $0}}' |wc -l >>depth/${id}.log;cat ${id} |sed '1d' |awk -F'\t' '{if($8>=4){print $0}}' |wc -l >>depth/${id}.log;cat ${id} |sed '1d' |awk -F'\t' '{if($8>=5){print $0}}' |wc -l >>depth/${id}.log;cat ${di} |sed '1d' |awk -F'\t' '{if($8>=6){print $0}}' |wc -l >>depth/${id}.log;cat ${id} |sed '1d' |awk -F'\t' '{if($8>=7){print $0}}' |wc -l >>depth/${id}.log;cat ${id} |sed '1d' |awk -F'\t' '{if($8>=8){print $0}}' |wc -l >>depth/${id}.log;cat ${di} |sed '1d' |awk -F'\t' '{if($8>=9){print $0}}' |wc -l >>depth/${id}.log;cat ${id} |sed '1d' |awk -F'\t' '{if($8>=10){print $0}}' |wc -l >>depth/${id}.log;cat ${id} |sed '1d' |awk -F'\t' '{if($8>=12){print $0}}' |wc -l >>depth/${id}.log;cat ${id} |sed '1d' |awk -F'\t' '{if($8>=16){print $0}}' |wc -l >>depth/${id}.log;cat ${id} |sed '1d' |awk -F'\t' '{if($8>=20){print $0}}' |wc -l >>depth/${id}.log;done结果如下:
2.5 筛选覆盖率大于 3 的 C 位点
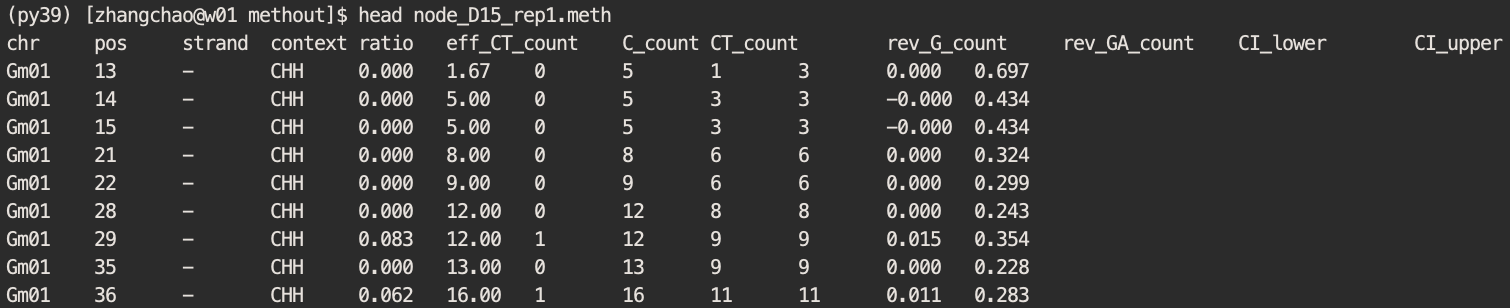
Section titled “2.5 筛选覆盖率大于 3 的 C 位点”ls *txt|cut -d '.' -f 1|while read id;donohup cat ${id}.txt |awk '$8>3{print$0}' > ${id}.meth &done结果如下:
2.6 计算转化率
Section titled “2.6 计算转化率”BS 处理不能保证将所有未甲基化的 C 转化为 T,因此存在部分误差;有两种途径可以计算转化率:(1)叶绿体不会发生甲基化,因此叶绿体中的甲基化均为建库误差;(2)对于没有叶绿体基因组的物种,可以在建库时加入 λ 噬菌体,它也不会发生甲基化。
(1)筛选出叶绿体中的位点
ls *meth |cut -d '.' -f 1|while read id;donohup cat ${id}.meth | grep 'GmC' |awk 'BEGIN{OFS="\t"}$13=1-$7/$8{print $1,$2,$7,$8,$13}' > ${id}.C &done(2)计算转化率
ls *C |cut -d '.' -f 1 |while read id;docat ${id}.C | awk '{a+=$3;b+=$4}END{print 1-a/b}' >> ratio.txtdone3、计算甲基化水平
Section titled “3、计算甲基化水平”3.1 转为 ViewBS 需要的格式
Section titled “3.1 转为 ViewBS 需要的格式”#methratio输出文件改为ViewBS文件的输入格式ls *meth|cut -d"." -f 1 | while read id;docat ${id}.meth |sed '1d' |awk '{$13=$8-$7}{print $1"\t"$2"\t"$3"\t"$7"\t"$13"\t"$4}' > ${id}_ViewBS.input;bgzip ${id}_ViewBS.input;tabix -C -p vcf ${id}_ViewBS.input.gz;done3.2 全基因组甲基化水平
Section titled “3.2 全基因组甲基化水平”ViewBS GlobalMethLev \--sample /pub4/zhangchao/Methylome_Soybean/BS-seq/viewbs/data/root_D15_rep1_ViewBS.input.gz,R15_1 \--sample /pub4/zhangchao/Methylome_Soybean/BS-seq/viewbs/data/root_D15_rep2_ViewBS.input.gz,R15_2 \--sample /pub4/zhangchao/Methylome_Soybean/BS-seq/viewbs/data/root_D15_merge_ViewBS.input.gz,R15_m \--sample /pub4/zhangchao/Methylome_Soybean/BS-seq/viewbs/data/node_D15_rep1_ViewBS.input.gz,N15_1 \--sample /pub4/zhangchao/Methylome_Soybean/BS-seq/viewbs/data/node_D15_rep2_ViewBS.input.gz,N15_2 \--sample /pub4/zhangchao/Methylome_Soybean/BS-seq/viewbs/data/node_D15_merge_ViewBS.input.gz,N15_m \--outdir meth_Global --prefix D153.3 基因区域的甲基化水平
Section titled “3.3 基因区域的甲基化水平”ViewBS MethHeatmap --region gene_info.txt \ #基因的位置信息,包括染色体、起始位置、终止位置、基因ID、正负链,可以从gff文件中提取--sample /pub4/zhangchao/Methylome_Soybean/BS-seq/viewbs/data/root_D15_merge_ViewBS.input.gz,R15 \--sample /pub4/zhangchao/Methylome_Soybean/BS-seq/viewbs/data/node_D15_merge_ViewBS.input.gz,N15 \--prefix gene \--cluster_row FALSE \--minDepth 3 \--context CG \ #CG、CHG、CHH分开计算--outdir Heatmap3.4 基因 metaplot
Section titled “3.4 基因 metaplot”ViewBS MethOverRegion --region gene_info.txt \ #基因的位置信息,包括染色体、起始位置、终止位置、基因ID、正负链,可以从gff文件中提取--sample /pub4/zhangchao/Methylome_Soybean/BS-seq/viewbs/data/root_D15_merge_ViewBS.input.gz,R15 \--sample /pub4/zhangchao/Methylome_Soybean/BS-seq/viewbs/data/node_D15_merge_ViewBS.input.gz,N15 \--outdir Metaplot \--prefix gene \--minDepth 3 \--binNumber 30 \--context CG #CG、CHG、CHH分开计算4、计算差异甲基化区域(DMR)
Section titled “4、计算差异甲基化区域(DMR)”4.1 转为 methlKit 需要的格式
Section titled “4.1 转为 methlKit 需要的格式”#methratio输出文件改为methylKit文件的输入格式ls *meth|cut -d"." -f 1 | while read id;donohup grep CG ${id}.meth | awk '{$14=($1 "." $2);$15=$5*100;$16=100-$5*100}{print $14 "\t" $1 "\t"$2 "\t" $3 "\t" $8 "\t" $15 "\t" $16}' > ${id}_CG.methylkit &nohup grep CHG ${id}.meth | awk '{$14=($1 "." $2);$15=$5*100;$16=100-$5*100}{print $14 "\t" $1 "\t"$2 "\t" $3 "\t" $8 "\t" $15 "\t" $16}' > ${id}_CHG.methylkit &nohup grep CHH ${id}.meth | awk '{$14=($1 "." $2);$15=$5*100;$16=100-$5*100}{print $14 "\t" $1 "\t"$2 "\t" $3 "\t" $8 "\t" $15 "\t" $16}' > ${id}_CHH.methylkit &doneR 脚本:
setwd("/path/to/methylkit")library(methylKit)
file.list = list(  "/path/to/root_D10_rep1_CG.methylkit",  "/path/to/root_D10_rep2_CG.methylkit",  "/path/to/node_D10_rep1_CG.methylkit",  "/path/to/node_D10_rep2_CG.methylkit"  )
myobj <- methRead(  file.list,  sample.id = list(    "R10-1_CG",    "R10-2_CG",    "N10-1_CG",    "N10-2_CG"    ),  assembly = 'root_nodule',  treatment = c(0,0,1,1),  context = "CG",  mincov = 4  )
tiles = tileMethylCounts(myobj, win.size = 100, step.size = 100, cov.bases = 4, mc.cores = 5)meth = unite(tiles, destrand = FALSE)myDiff = calculateDiffMeth(meth, mc.cores = 5)myDiff_m = getMethylDiff(myDiff, difference = 40, qvalue = 0.01)
write.table(myDiff_m,  file="/path/to/R10_N10_CG_DMR",  quote=F, sep = "\t", row.names = F  )
Rscript R10_N10_CG_DMR.R